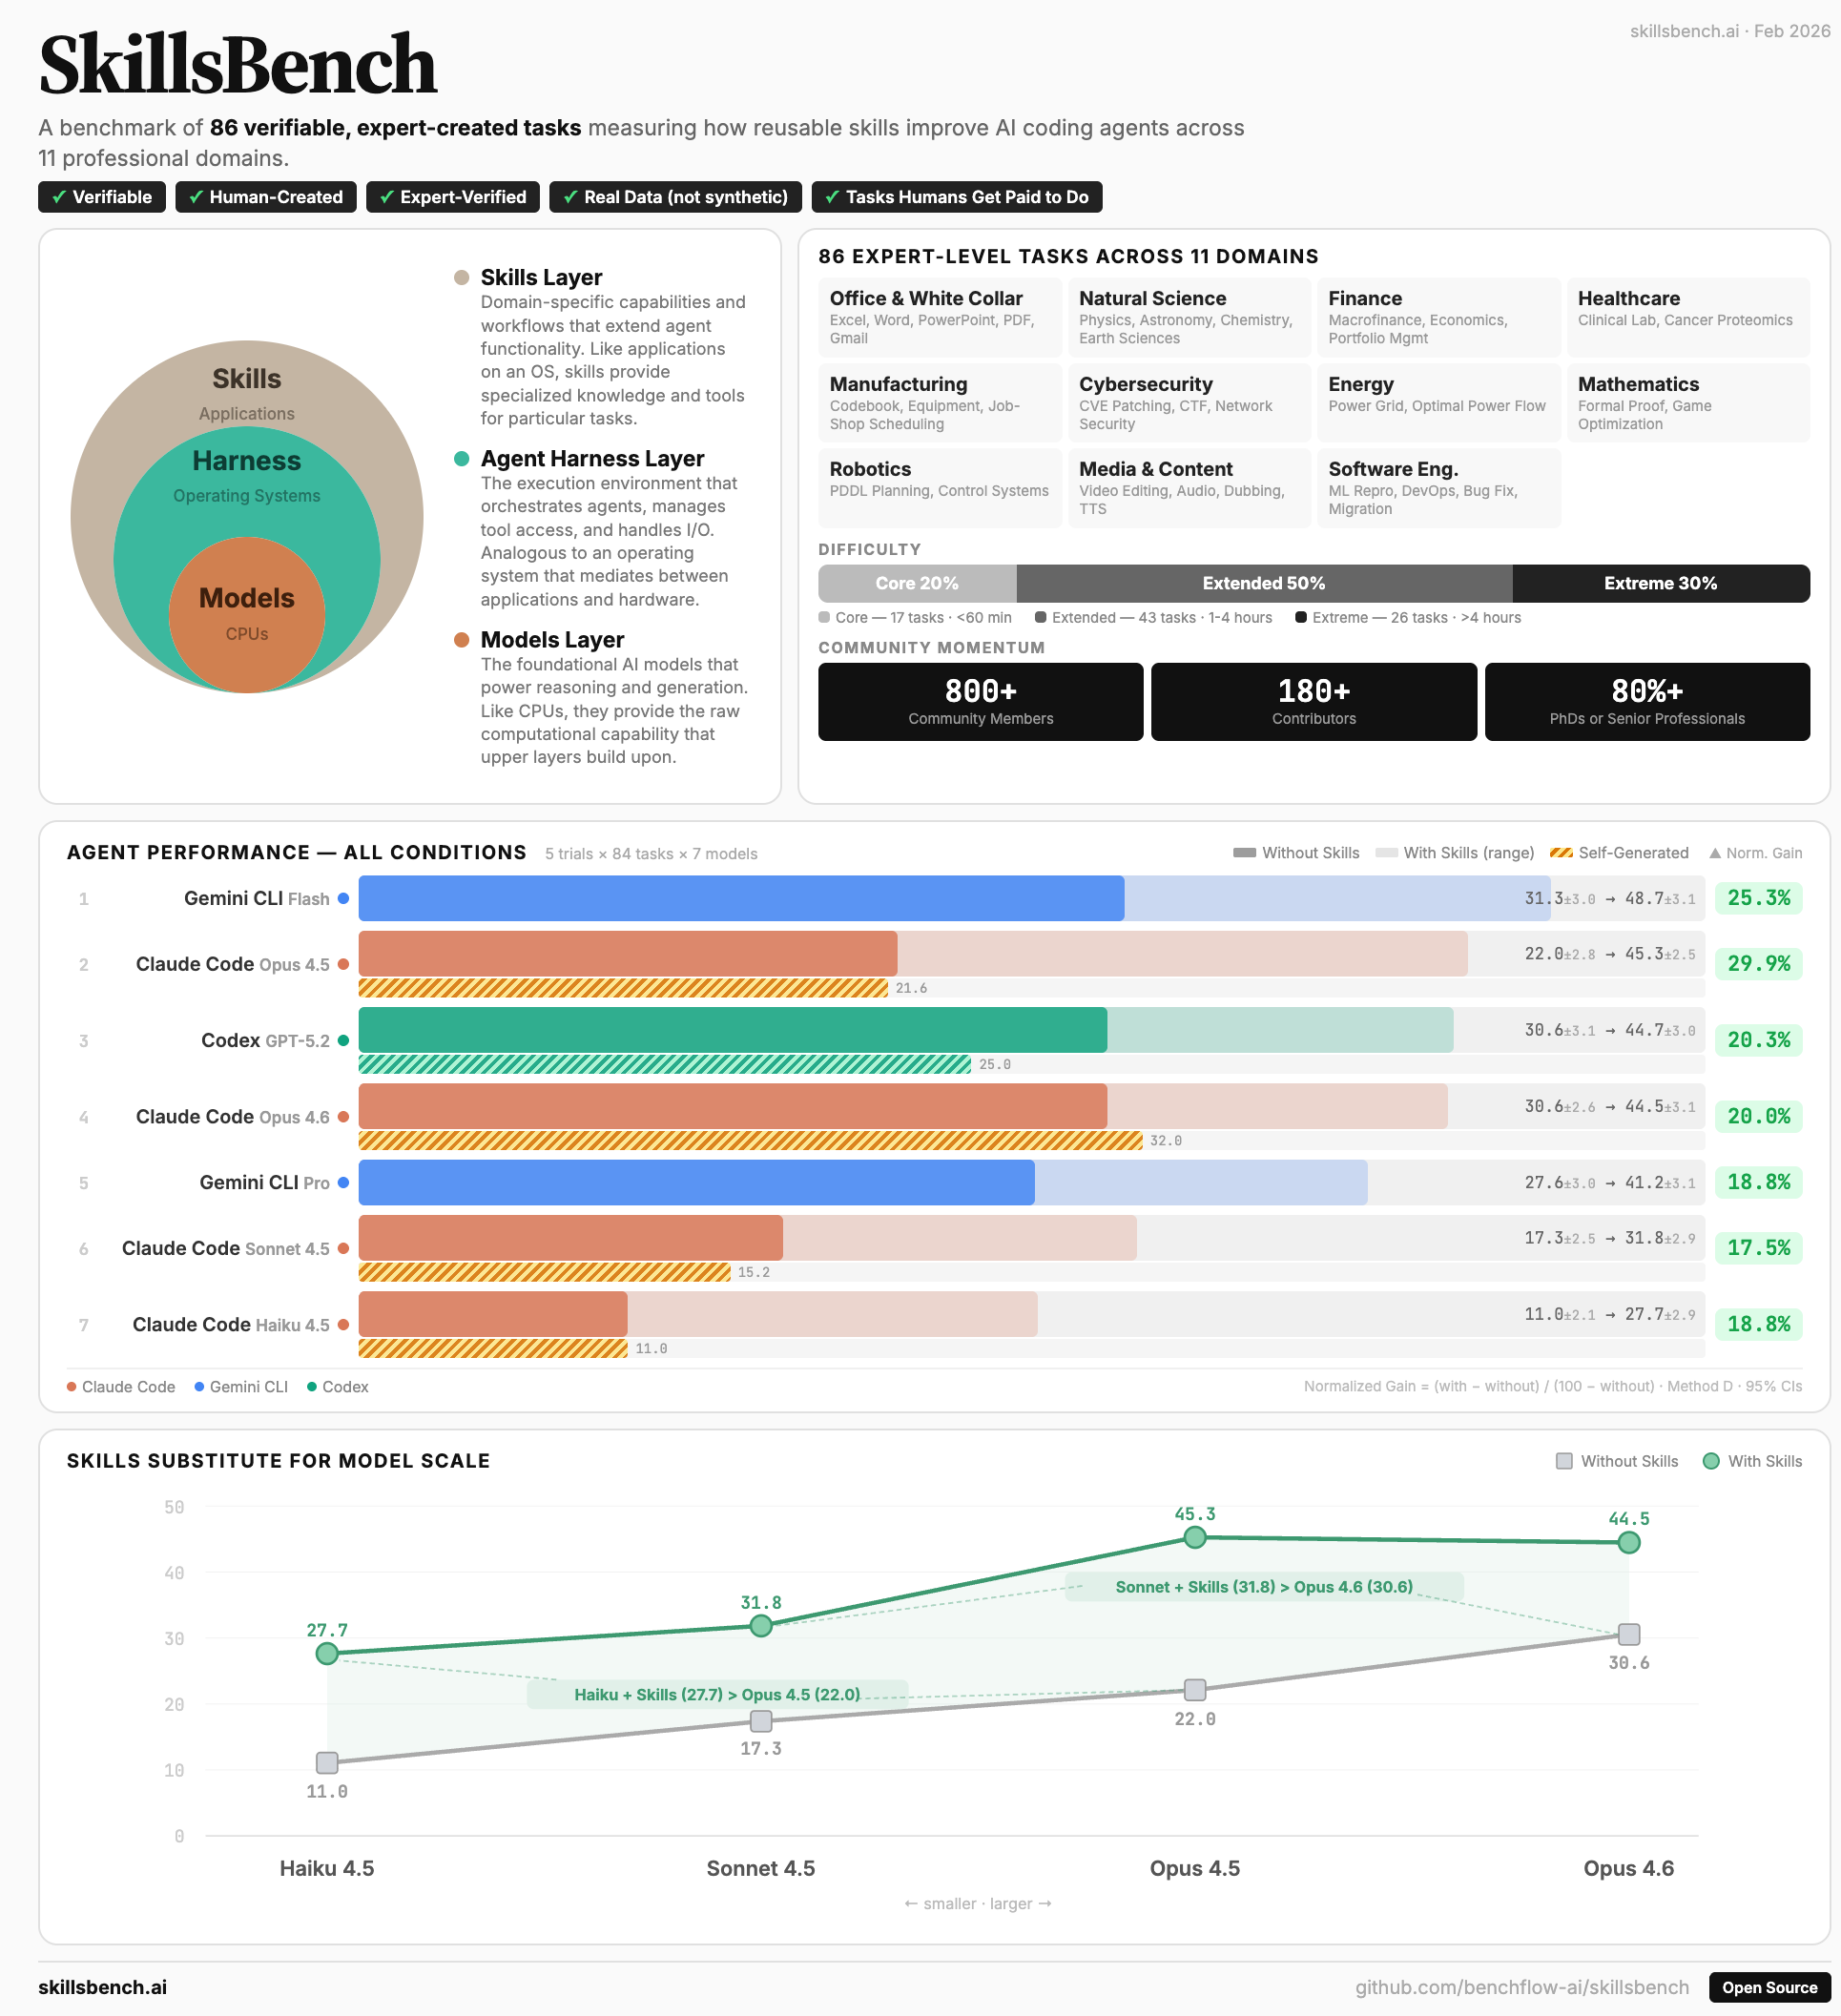
A benchmark for testing whether procedural knowledge packaged as reusable skills translates into real agent capability. Curated tasks and deterministic verifiers compare agents with and without skills, separating skill quality from an agent’s ability to discover and apply them. Used in frontier-model evaluations.
Lin Shi, Haowei Lin, Zixuan Zhu, Xiaoyue Zhou, et al. (including Junwei He)
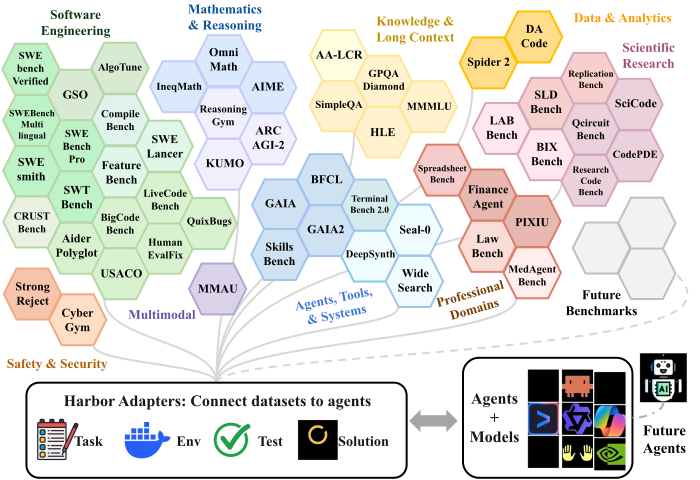
Unified adapters for 80+ agentic benchmarks, with evaluation across 54 benchmarks. Harbor-Index curates 82 tasks from 29 benchmarks into a compact meta-dataset, making diverse agent evaluation easier to reproduce and compare.