I work on foundation models and agentic intelligence at ByteDance. My research focuses on agentic reinforcement learning, agent architectures, embodied intelligence, and physical intelligence.
I enjoy exchanging ideas and working with people across research and engineering. I’m especially excited about foundation models, agentic RL, embodied and physical intelligence, and agents that learn through real-world interaction. Whether you’re working in these areas or simply curious, I’d love to hear from you. Say hello by email ↗
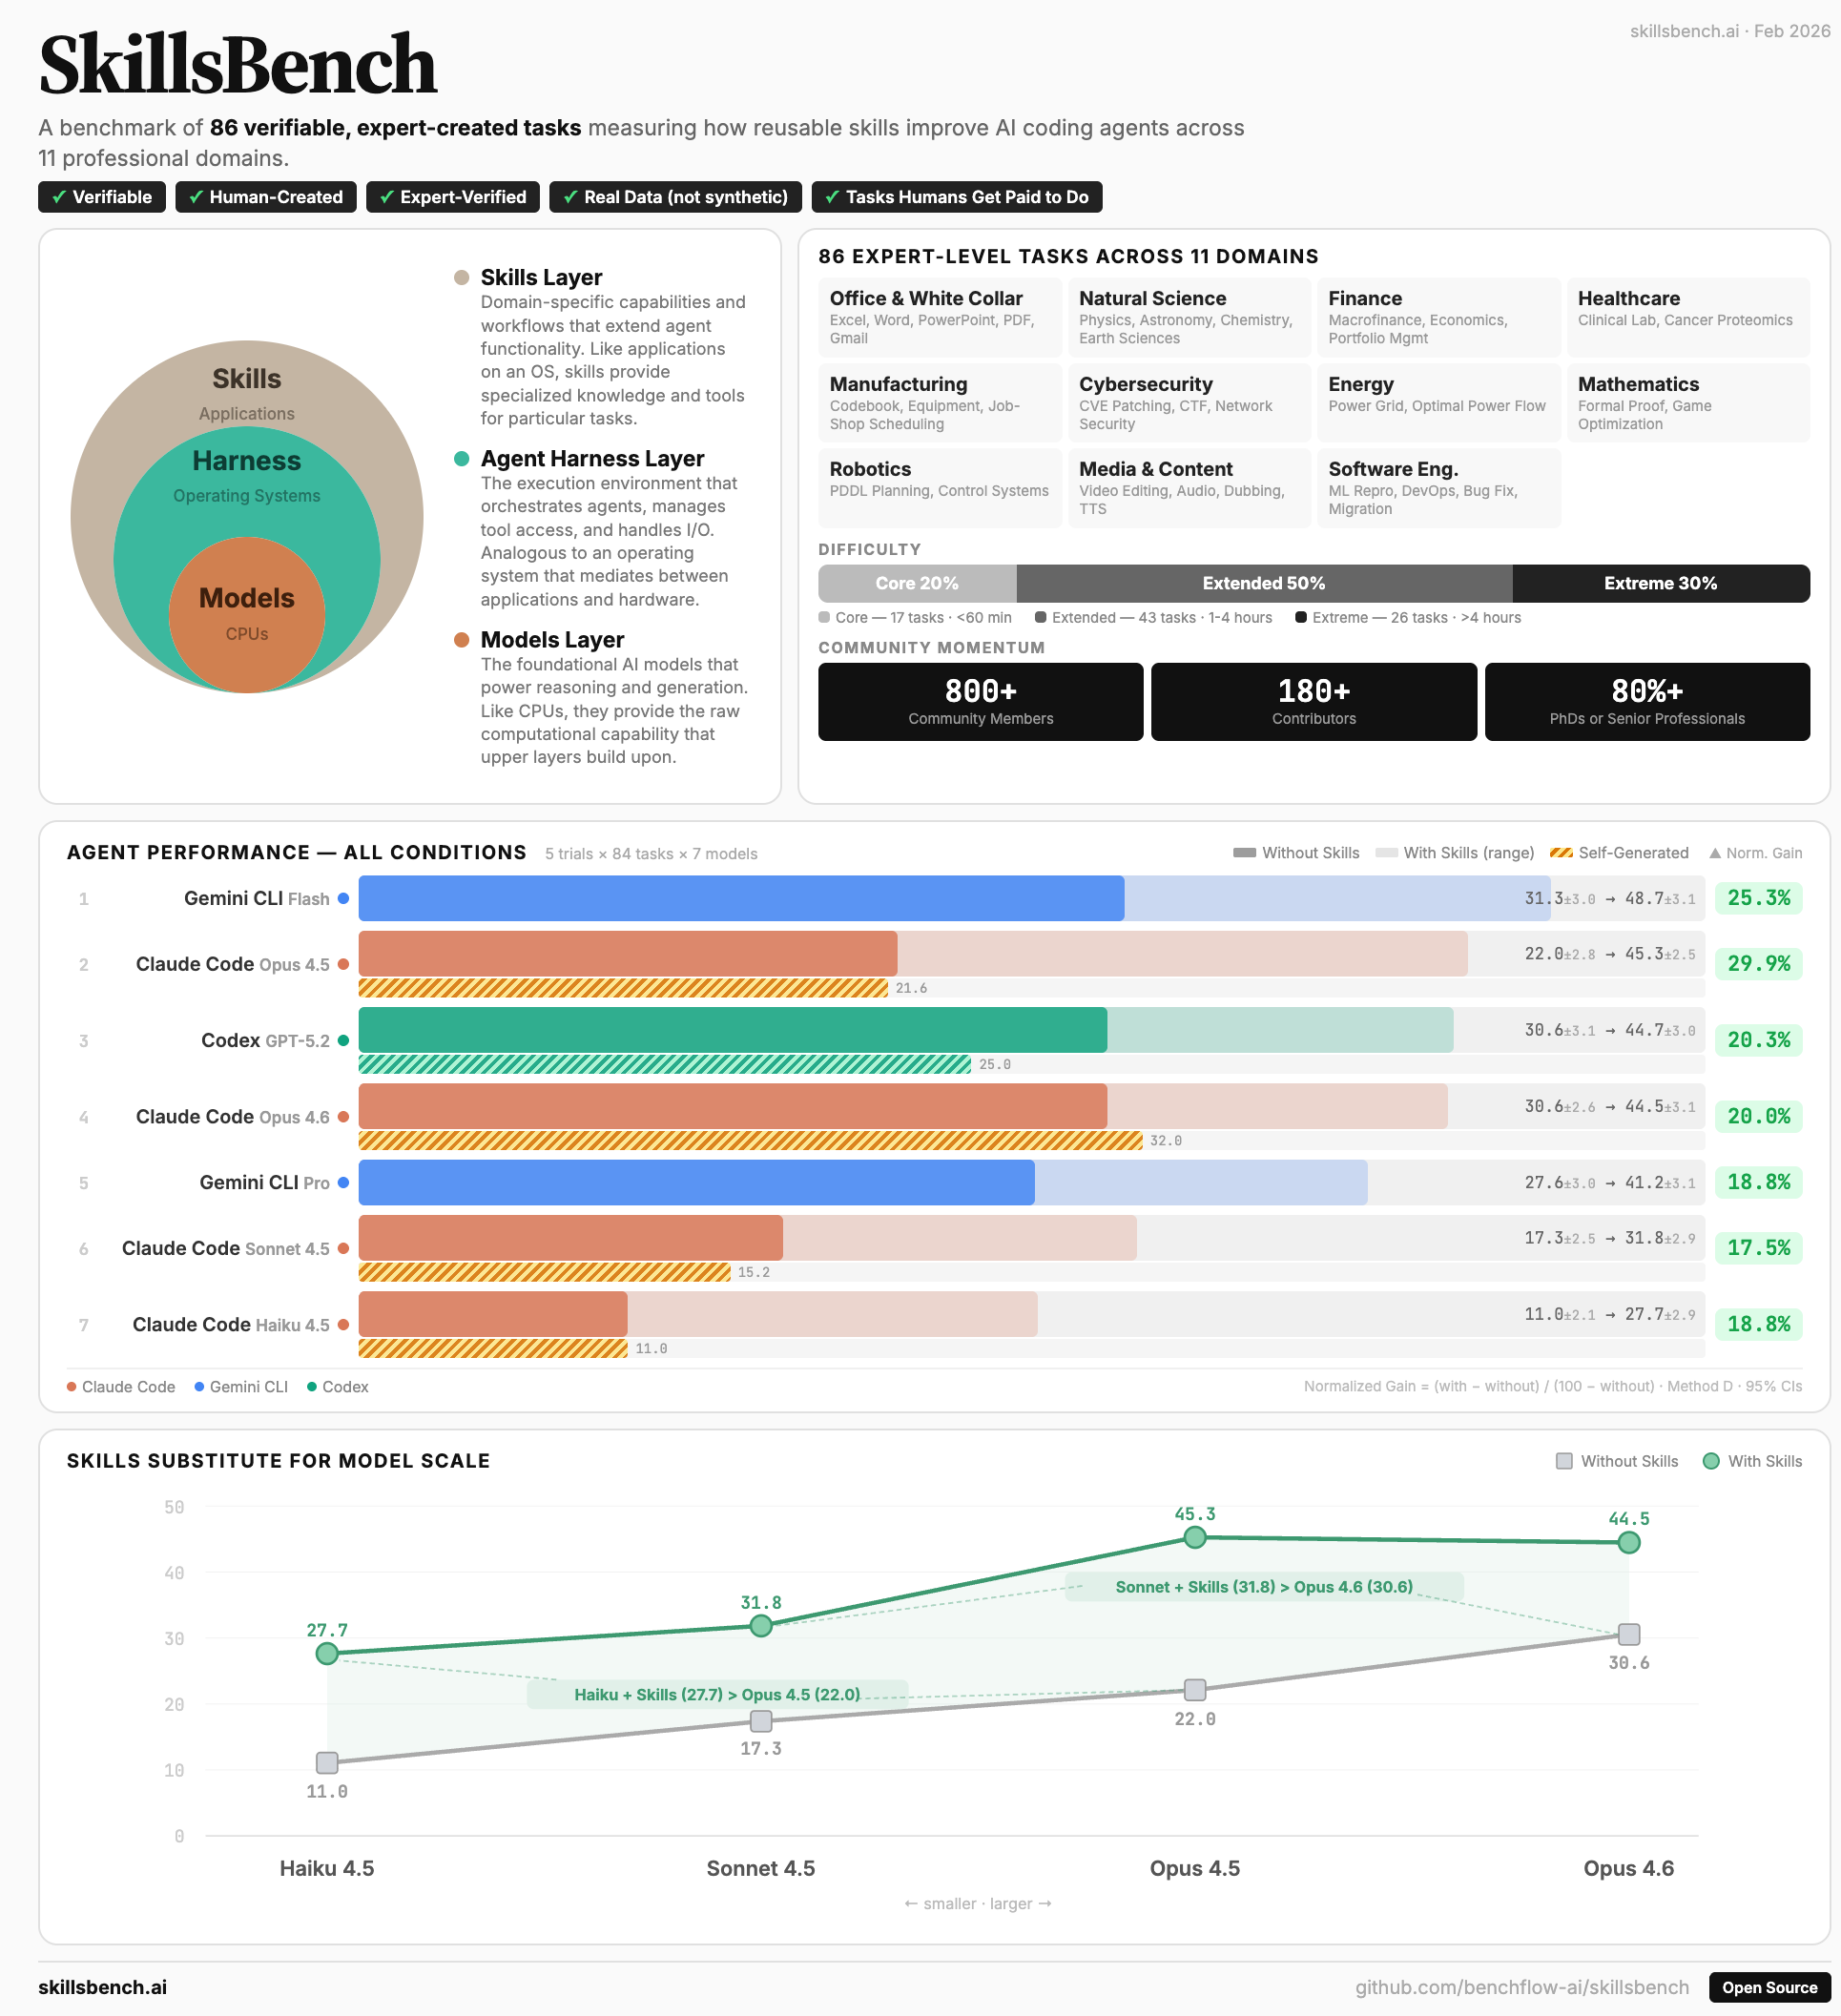
A benchmark for testing whether procedural knowledge packaged as reusable skills translates into real agent capability. Curated tasks and deterministic verifiers compare agents with and without skills, separating skill quality from an agent’s ability to discover and apply them. Used in frontier-model evaluations.
Lin Shi, Haowei Lin, Zixuan Zhu, Xiaoyue Zhou, et al. (including Junwei He)
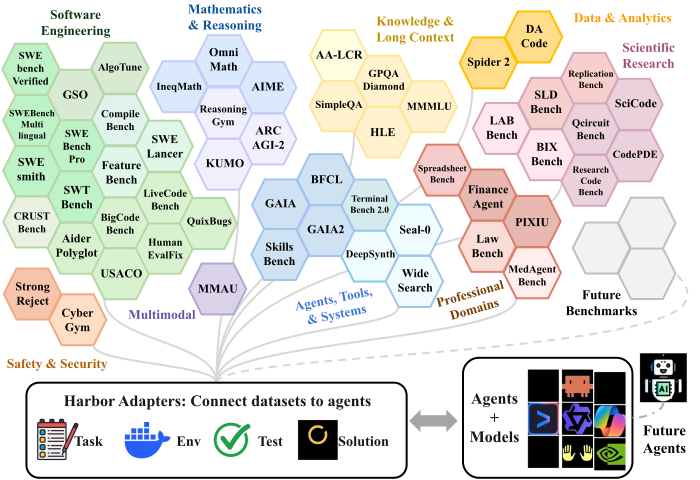
Unified adapters for 80+ agentic benchmarks, with evaluation across 54 benchmarks. Harbor-Index curates 82 tasks from 29 benchmarks into a compact meta-dataset, making diverse agent evaluation easier to reproduce and compare.
 ByteDance. My research focuses on agentic reinforcement learning, agent architectures, embodied intelligence, and physical intelligence.
 Institute of Computing Technology, Chinese Academy of Sciences
 Harbin Institute of Technology


 Hainan Island (1,000+ km) and
 Taihu Lake (400+ km).
